TRANSFAC WorkspaceThe gold standard of transcriptional regulation
The most comprehensive transcription-factor resource in eukaryotes — now a single, complete workspace solution for gene regulation, signaling networks and disease & drug discovery.
- Manually curated
- Used by researchers around the globe
- Integrated with more than 200 bioinformatics tools and pipelines
Design your workspace — tell us your needs (biological system, type of experiments, data type, length of your project) and we’ll build the package around your requirements.
Data manually curated from scientific publications
From a list of genes to the mechanisms, targets and treatments behind them
Regulation is hidden in the genome
Transcription-factor binding sites, their combinations, the promoters and enhancers that control your genes are scattered across the genome and buried in the literature.
Signals span whole networks
Understanding why a gene acts as it does means reconstructing the signaling and metabolic cascades upstream of its regulators — across millions of reactions.
Translation demands integration
Turning findings into drug targets, biomarkers and treatment options requires linking mechanisms to diseases, drugs and clinical trials — and doing it with or without coding.
One workspace for the complete regulatory journey
- Which transcription factors regulate them?
- Where are the relevant binding sites?
- Which promoters and enhancers are involved?
- Which combinations of transcription factors may be active?
- Which signaling pathways control those transcription factors?
- Which upstream molecules act as master regulators?
- How do different omics layers fit together?
- Which molecular mechanisms may be driving a disease?
- Which biomarkers or therapeutic targets should be investigated next?
TRANSFAC Workspace connects these layers in one integrated research environment. Start with a gene, a regulatory sequence, a list of differentially expressed genes, genomic variants or multi-omics data — then move through the biology, step by step.
- Gene regulation
- Transcription factors
- Signaling and metabolic pathways
- Master regulators
- Disease mechanisms
- Biomarkers and prospective drug targets
From motif analysis to drug targets
Watch Prof. Dr. Alexander Kel take one enriched motif all the way to disease mechanisms and prospective drug targets — in under two minutes.
You decide where to start, how deeply to analyze and how to build your workflow.
You set the variables —
- experiments
- seats
- storage
- usage time
— we’ll shape a package that fits.
An integrated environment where your data and our knowledge, tools and workflows work together
TRANSFAC Workspace unites the TRANSFAC knowledge base with the geneXplain platform and the full analysis suite: discover transcription-factor binding sites, reconstruct signal-transduction and metabolic networks, and identify disease mechanisms, drug targets and treatments — from raw multi-omics data through to detailed result tables and a publication-ready report.
IncludesKnowledge base
 TRANSFAC Database
 TRANSPATH Database
 HumanPSD Database
Platform
 geneXplain platform
Analysis suite
 MATCH Suite
 Pathway Omics Suite
 Disease Omics Suite (Genome Enhancer)
 PathFinderProtein Genome Map
Every capability below is included in TRANSFAC Workspace. They build on one another — from binding sites, to the networks around them, to the diseases and drugs they drive.
Three domains of analysis, one seamless workflow
01 · Gene regulation & TFBS — discover TF binding sites in the promoters and enhancers of your genes
A comprehensive solution for gene-regulation analysis, powered by the world’s largest curated encyclopedia of transcriptional regulation.
Other motif tools ask, “Which TF could bind here?” TRANSFAC Workspace also asks, “Which TF is likely to be active here, in this cell type, under this disease condition — and what upstream mechanism activates it?”
Predict transcription-factor binding sites and their combinations across genomic sequences using more than 10,000 positional weight matrices, advanced Machine Learning methods, and matrix-specific quality thresholds that help control false-positive and false-negative predictions.
Access experimentally characterized binding sites, large-scale ChIP data, regulated genes, and detailed promoter, enhancer and silencer annotations. Identify tissue- and cell-type-specific regulatory units and combinations of transcription factors that may control your genes.
Use a complete set of promoter-analysis tools — from custom pipelines for bioinformaticians to automated, no-code workflows for biomedical researchers — integrated with multi-omics analysis in the geneXplain Platform.
02 · Pathways & networks — reconstruct the signal-transduction network controlling your genes
A comprehensive knowledge base on signal transduction and metabolic pathways — with the master-regulator analysis that turns patterns into causes.
Predict the pathways targeting the genes of your interest and build customized regulatory and metabolic networks based on over one million reactions extracted from the original scientific literature and evaluated by experts.
Apply integrated pathway visualization and modification, and reconstruct master regulators upstream of your transcription factors using a modern graph algorithm.
Perform Upstream Analysis — integrated promoter and pathway analysis — for the identification of prospective drug targets and biomarkers, within the geneXplain platform.
03 · Disease & drug discovery — identify drug targets and disease biomarkers, even for complex clinical cases
Treatments for complex clinical cases with pathology unresponsive to conventional therapies.
No bioinformatics skills needed — run complicated omics data-processing pipelines with just a few clicks in a user-friendly interface, and get drug-repurposing suggestions driven by networks and chemoinformatics.
Automatically process multi-omics raw patient data and identify prospective drug targets and treatments predicted to be effective for the studied clinical case.
Reconstruct disease molecular mechanisms in full, based on integrated promoter and pathway analysis for over 2,700 human diseases.
Use expert curated disease-biomarker knowledge to distinguish causal, correlative and mechanism-of-action biomarkers, place them in their biological and clinical context, and connect them to supporting evidence, molecular pathways, drugs and clinical studies.
From raw data to a publication-ready report, in one platform
Bring your data
Upload genes, FASTA, FASTQ, VCF or BED, and omics data from RNA-seq, ChIP-seq, ATAC-seq, CUT&RUN, WGS, WES and single cell.
Analyze in the platform
Run 200+ tools and pipelines in the geneXplain Platform through an easy no-code GUI, or drive everything via the API from Python and R.
Find binding sites
Predict TF binding sites and their combinations with the MATCH Suite, over 10,000 PWMs and built-in ML.
Reconstruct networks
Build regulatory and metabolic networks, search master regulators upstream of your TFs, and model them with SBGN diagrams and ODE simulation.
Translate to disease
Discover putative disease mechanisms, biomarkers and drug targets, and identify known or repurposed treatments.
Genome Enhancer
Automated enhancement of genomic and multi-omics data turned into mechanistic and therapeutic insight. In one workflow it elevates raw molecular data to an understanding of disease mechanisms, key transcription factors, master regulators, pathways, biomarkers and drug targets, and generates mechanism-based treatment hypotheses. Results are delivered in a publication-ready report and, for supported cancers, a Molecular Tumor Board report.
One resource, from basic research to translational discovery
Map gene regulation
Discover the transcription-factor binding sites — and their combinations — in the promoters and enhancers of your genes.
Reconstruct networks
Rebuild the signal-transduction and metabolic networks controlling your genes and pinpoint their master regulators.
Find targets & treatments
Identify drug targets and disease biomarkers, and surface known or repurposed treatments for complex clinical cases.
Ready to size it for your project?
Tell us the biological system, the experiments and the data — we will build the package around them.
Built for the whole lab, from the bench to the command line
No coding required — bench biologists & biomedical researchers
Run complicated omics pipelines from a few clicks in a user-friendly GUI. Fully automated, one-click solutions take you from raw data to a comprehensive report — no bioinformatics skills needed.
Full control & the API — core bioinformaticians
Build customized analysis pipelines across 200+ tools, integrate five omics layers, and run everything from your local Python and R via the API — with flexible cloud workspace sizes.
The reference knowledge base for eukaryotic gene regulation
TRANSFAC Workspace is the gold-standard resource for deep analysis of eukaryotic gene regulation.
Knowledge is curated by trained experts from full primary publications, linked to source articles and assigned evidence-based quality levels for binding sites and molecular reactions.
This enables researchers to focus analyses on the most reliable evidence.
Cited in more than 30,000 scientific publications, TRANSFAC also provides a distinctive PWM quality framework, with matrix-specific thresholds evaluated to reduce false-positive and false-negative TF-site predictions.
It supports tissue- and cell-type-specific TF regulatory units and goes beyond motif scanning by connecting regulatory sites and TF combinations to signaling pathways, master regulators, diseases, biomarkers and prospective drug targets.
The gold standard, by construction
Manually curated
Make better decisions with biological knowledge you can trust
High-quality, manually curated evidence helps you filter out noise, identify the most relevant mechanisms, prioritize stronger targets and biomarkers, and generate hypotheses worth validating experimentally.
Every curated fact is traced to the original scientific publication and supported by evidence-based quality assessment — so you can understand not only what is known, but how strongly it is supported.
This depth of evidence, curation and biological context is simply not available from free resources alone.
TRANSFAC® curation from sites to DNA-binding models
• Alignment & optimization based on standard performance (e.g. AUC)
TRANSPATH® curation from literature evidence to mechanistic reactions
Quality advantage: TRANSPATH captures who acts on whom, how, with what evidence, and in which biological context.
HumanPSD™ disease curation from literature evidence to structured disease mechanisms
Quality advantage: HumanPSD™ disease curation captures not only whether a protein is linked to a disease, but how strongly the literature supports biomarker, mechanism or target relevance.
Experimentally validated
Functional TF binding sites confirmed by multiple experiments and the most comprehensive collection of ChIP-seq sites; over 1.2M reactions extracted from primary literature and evaluated by experts.
Broad & deep
- 300+species
- >10,000PWMs
- >2,700human diseases
- >10,000drugs
- >55,000targets
Continuously updated
Almost 40 years of continuous updating, several times a year. Versioned release statistics published for TRANSFAC, TRANSPATH, Protein Genome Map and HumanPSD.
TRANSFAC matrices are systematically benchmarked on genome-wide binding data
TRANSFAC provides a distinctive PWM quality framework, with matrix-specific thresholds evaluated to reduce false-positive and false-negative TF-site predictions. Having introduced its matrix evaluation in 2018, TRANSFAC was the first database to implement and regularly carry out a systematic model comparison on genome-wide binding data.
What sets the TRANSFAC matrix evaluation apart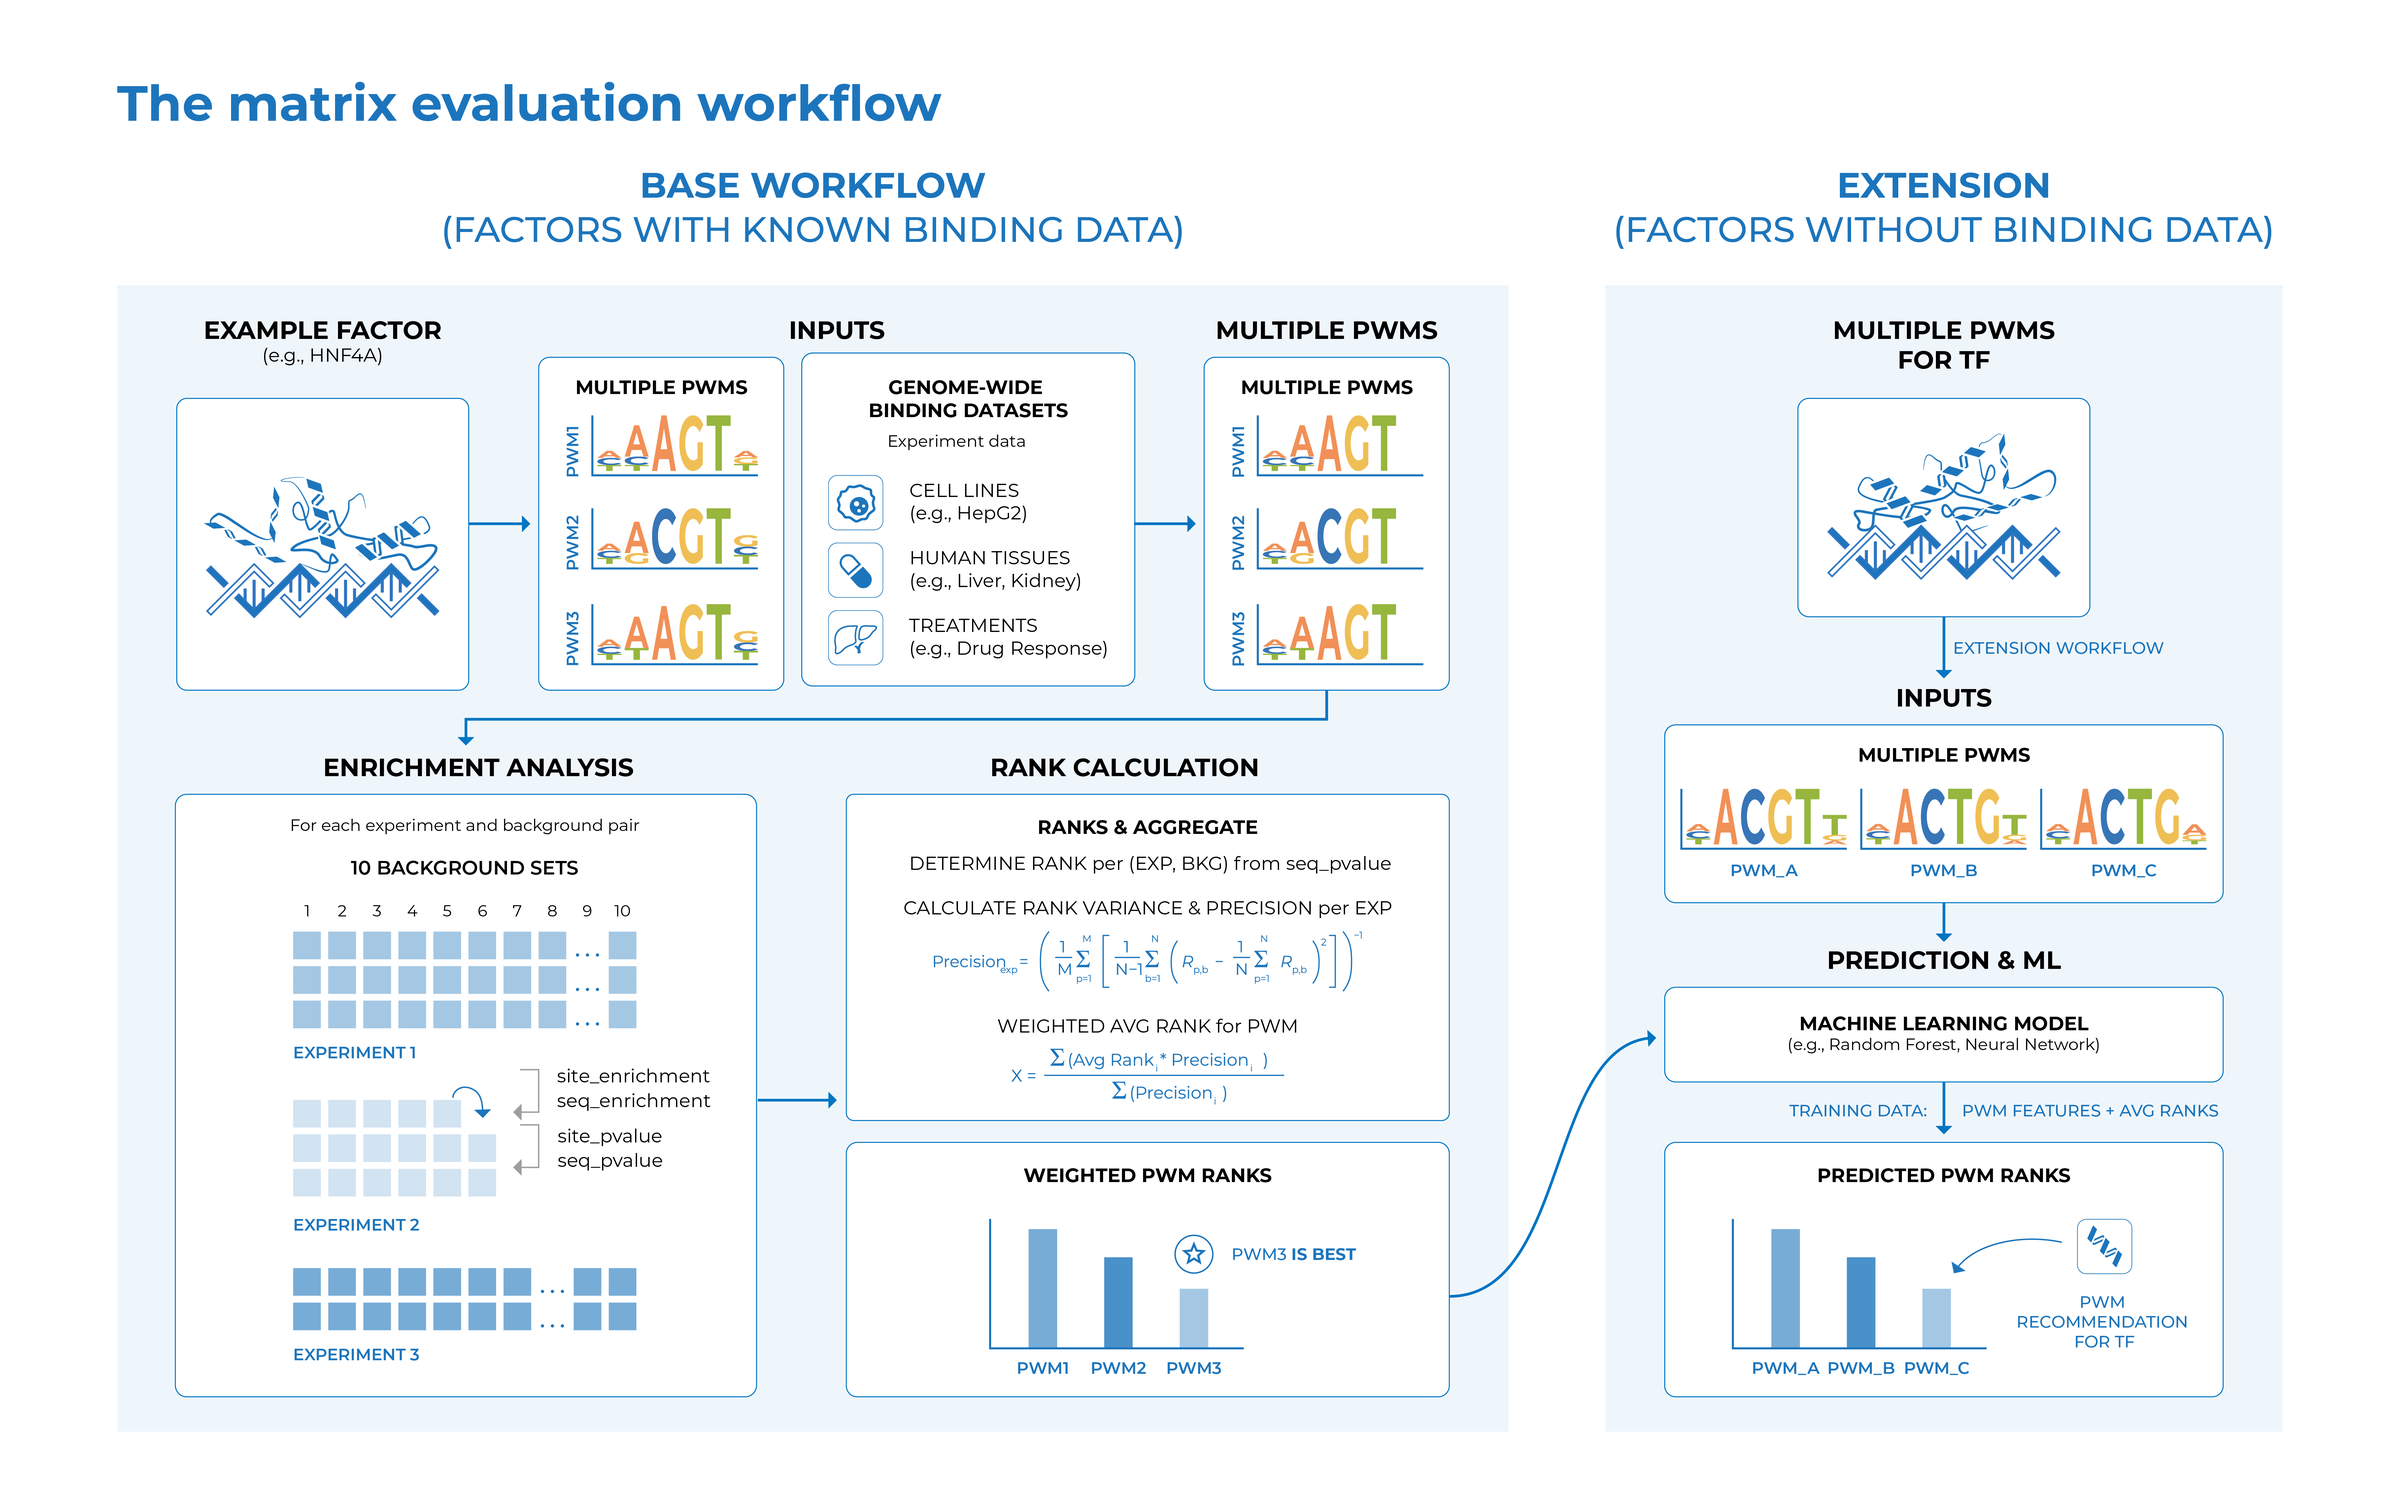
The matrix evaluation workflow: enrichment analysis and weighted PWM ranking, with a machine-learning extension for factors without genome-wide binding data. Tap to enlarge.
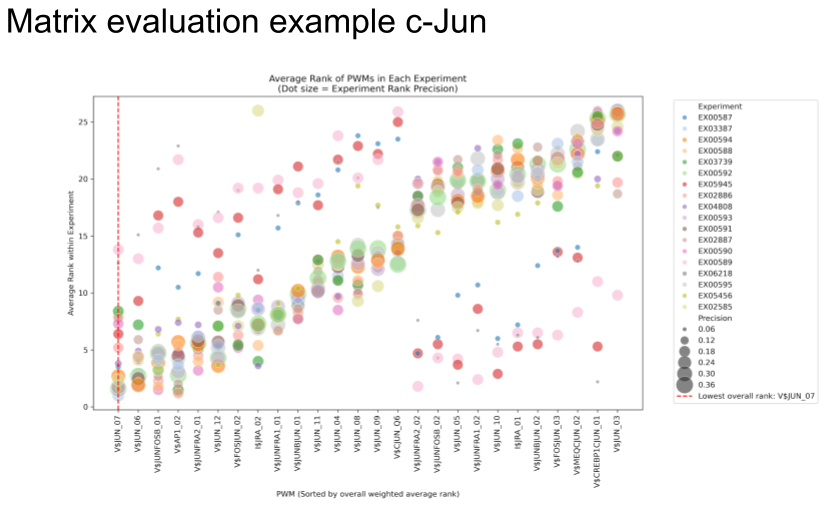
Matrix evaluation example: average rank of PWMs for c-Jun across experiments, dot size showing rank precision. Tap to enlarge.
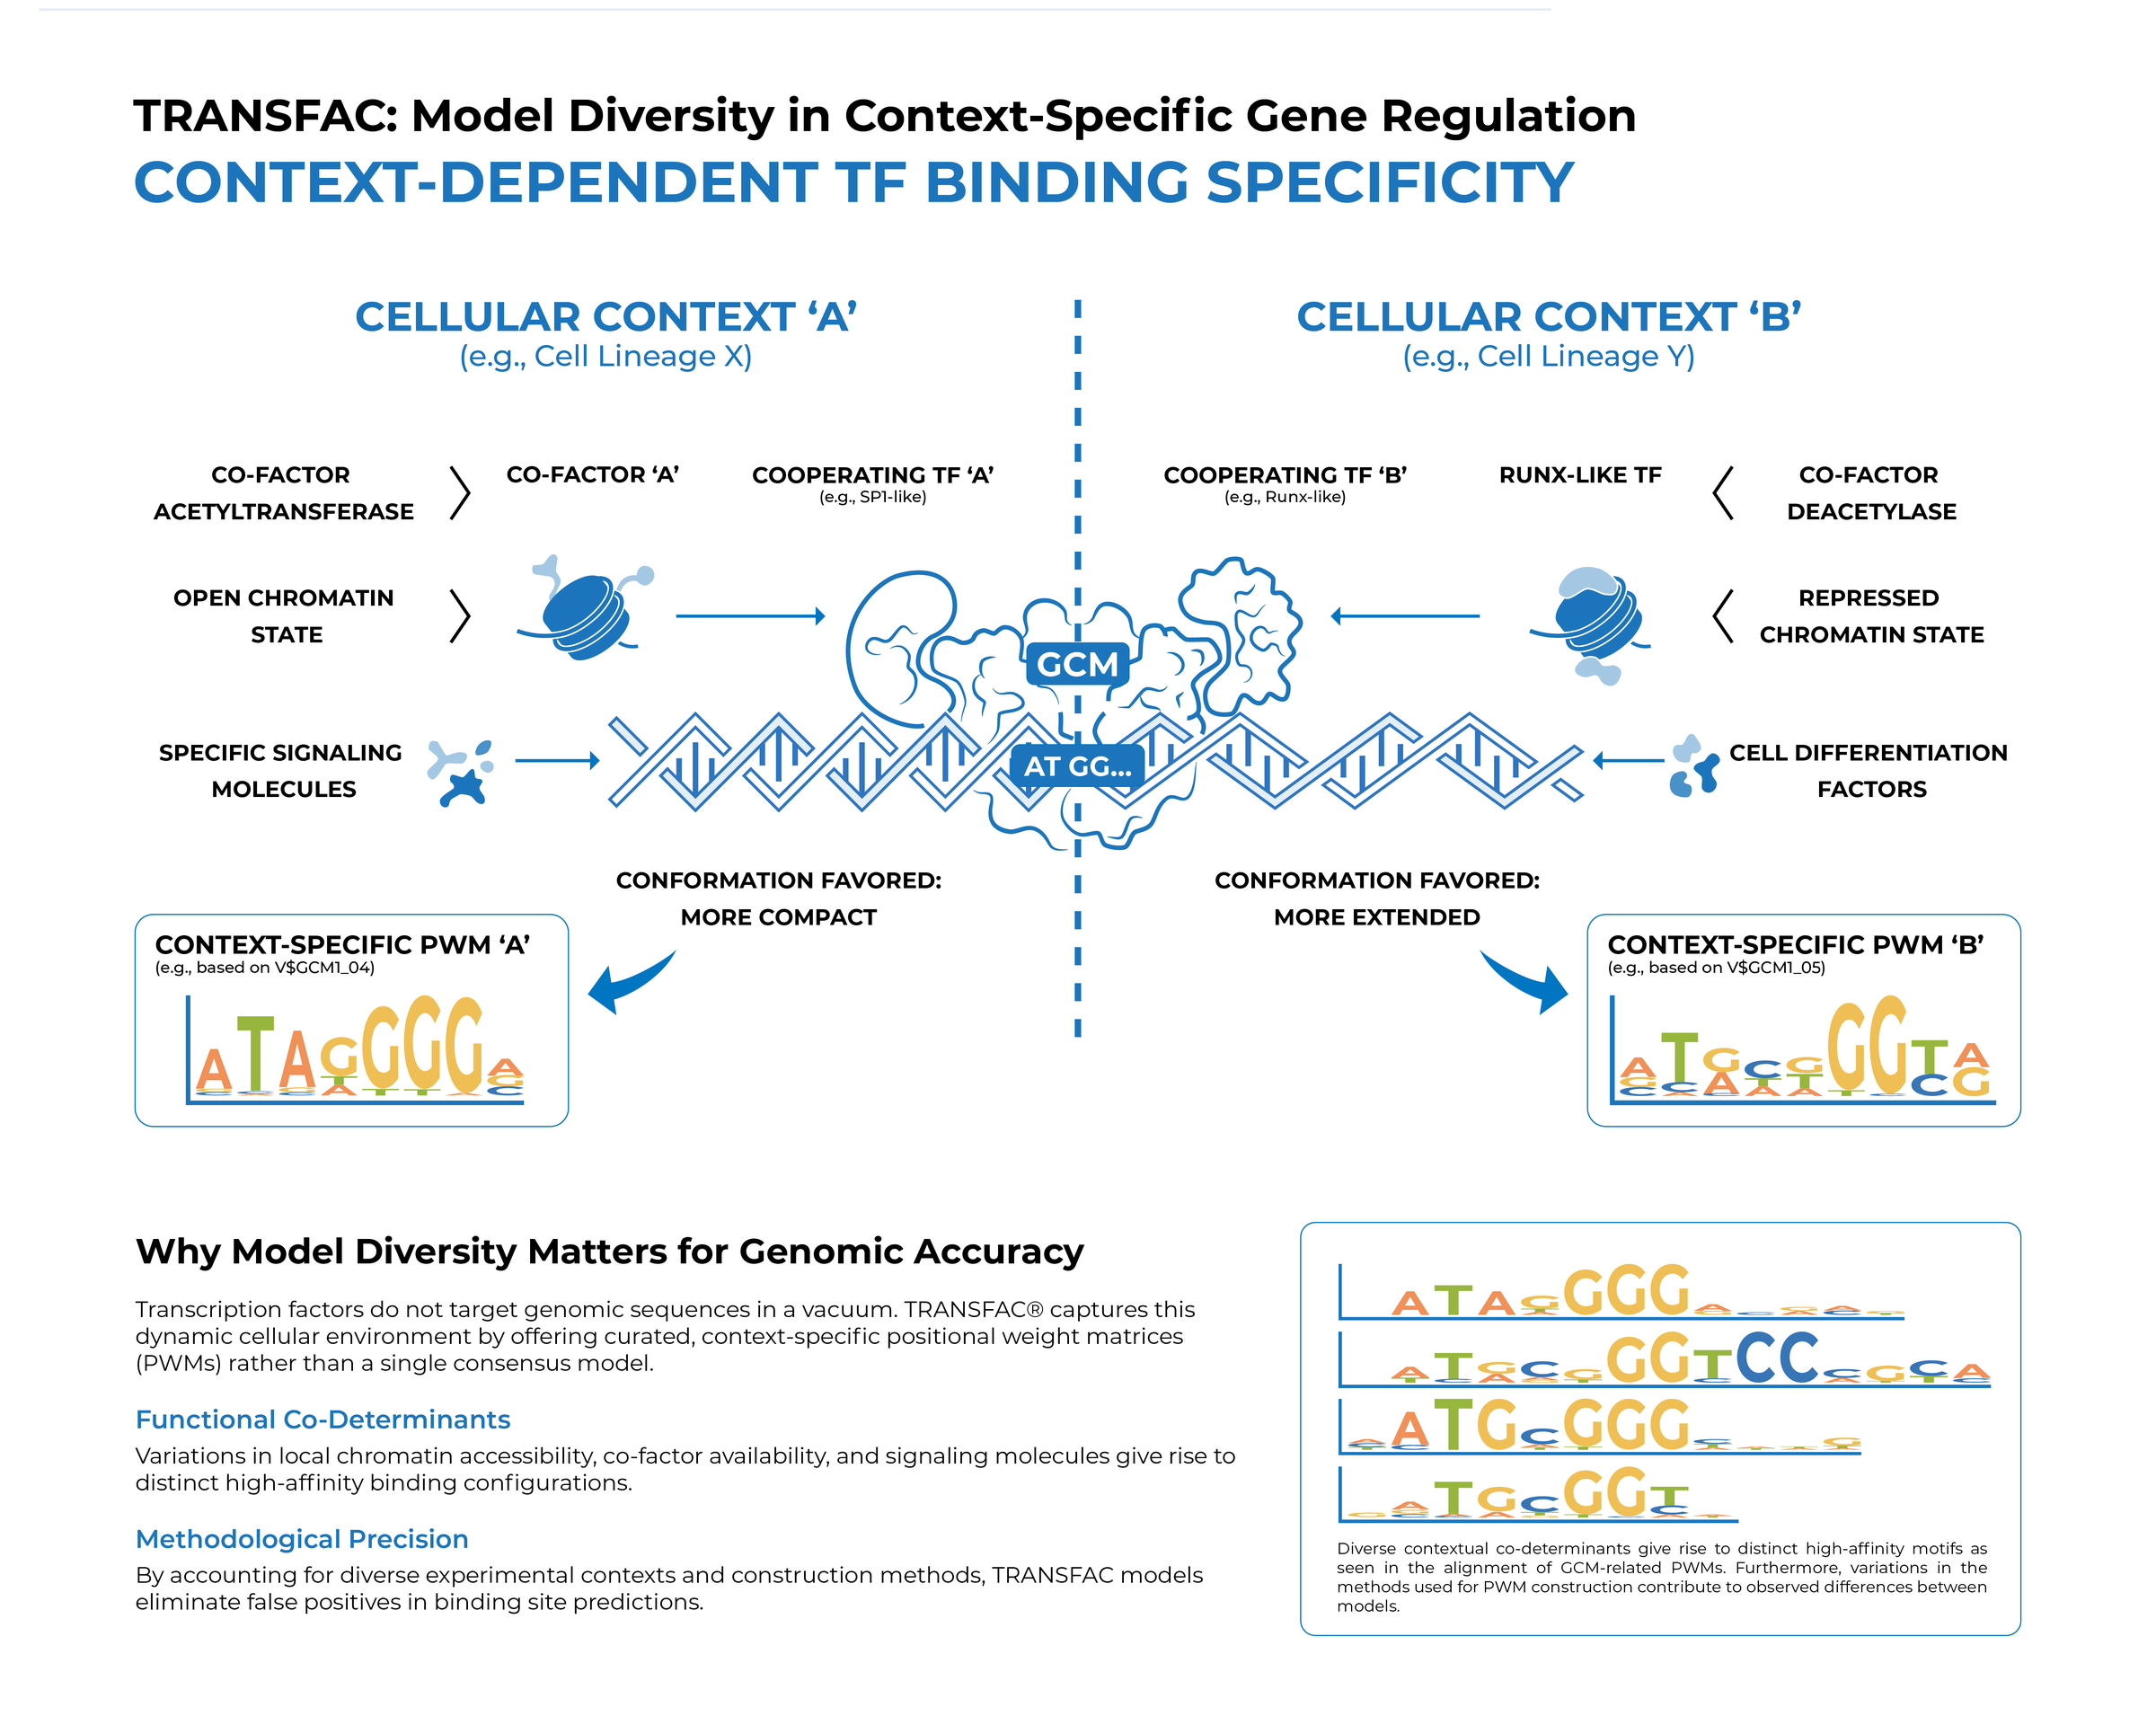
Model diversity in context-specific gene regulation: why TRANSFAC curates context-specific PWMs rather than a single consensus model. Tap to enlarge.
Questions, answered
Maximize your potential with the gold standard of transcriptional regulation
One package. Every database, tool and workflow. From a list of genes to the mechanisms, targets and treatments behind them.
One complete package — on purpose. Its full-scale functionality is where the value is: every database and tool works together, so you get more from your data — and better value for money — than assembling the pieces yourself. What we tailor to you is the scale, not the features.
- Number of seats
- Storage space
- Usage time
Configure your TRANSFAC Workspace
Tell us about your research so we can recommend the right setup.
Design your workspace — tell us your needs and we’ll shape the configuration that fits.